The GPU rig
One 96GB Blackwell + two 3090s for KV cache: the tinkerer's 30k answer at half the price.
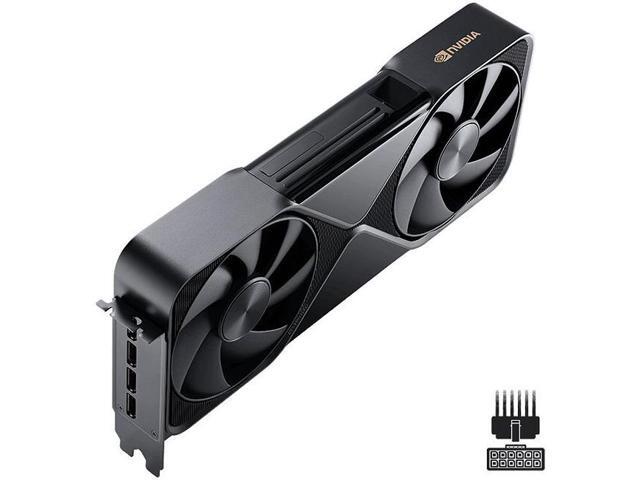
The path the 'three 170hx' commenters were pointing at, one generation newer. A 96GB RTX PRO 6000 runs the 100B-class models with room left, and stacked cheap 3090s act as extra KV-cache memory so long contexts do not strangle the big card. Loudest option, most flexible, and the upgrade path is a PCIe slot, not a new computer.
You read the phrase KV cache and felt curious, not scared. You want the fastest responses money can buy at this size, you want CUDA the day a model drops, and you do not mind a machine that sounds like it means it. This is the tinkerer tier: swap cards, quantize things yourself, reroute the 3090s as cache when a model needs more room.
first check: next Monday
The parts
What it runs
The 400B+ MoE class at usable quality: GLM 5.3 full is 371GB at 4-bit. Kimi K3 at 2.8T is 700GB at 2-bit - nothing in a desktop holds it.
Plan 1,100 to 1,300W at the wall at full tilt: that is a dedicated circuit conversation, not a power strip. Three GPUs at load sound like a hair dryer in another room. You will think about dust filters, and you should.
Three boxes, 384GB of pooled memory, CUDA-native. The models that need a rack are the models that do everything, and this is the smallest room they fit in. Batch workloads, agent fleets, a family of services all answering from your own hardware.
See the $20k tier →