Run AI on hardware you own - and follow the models worth running
Stop renting intelligence. Find open models that fit your rig, benchmarked honestly, with a source-cited tracker of who runs what - so no vendor or government order can switch off the model you depend on.
Latest open-weight models
Browse all modelsLatest news & guides
All guidesThe local intelligence frontier
You don't need a cloud API to run the best open-weight models. A single high-memory machine or multi-GPU desktop runs Llama, Qwen, GLM, and more privately - no per-token bill, no rate limit, and no vendor switch-off.
Explore the full frontier →Latest AI tooling
Latest rigs
All rigs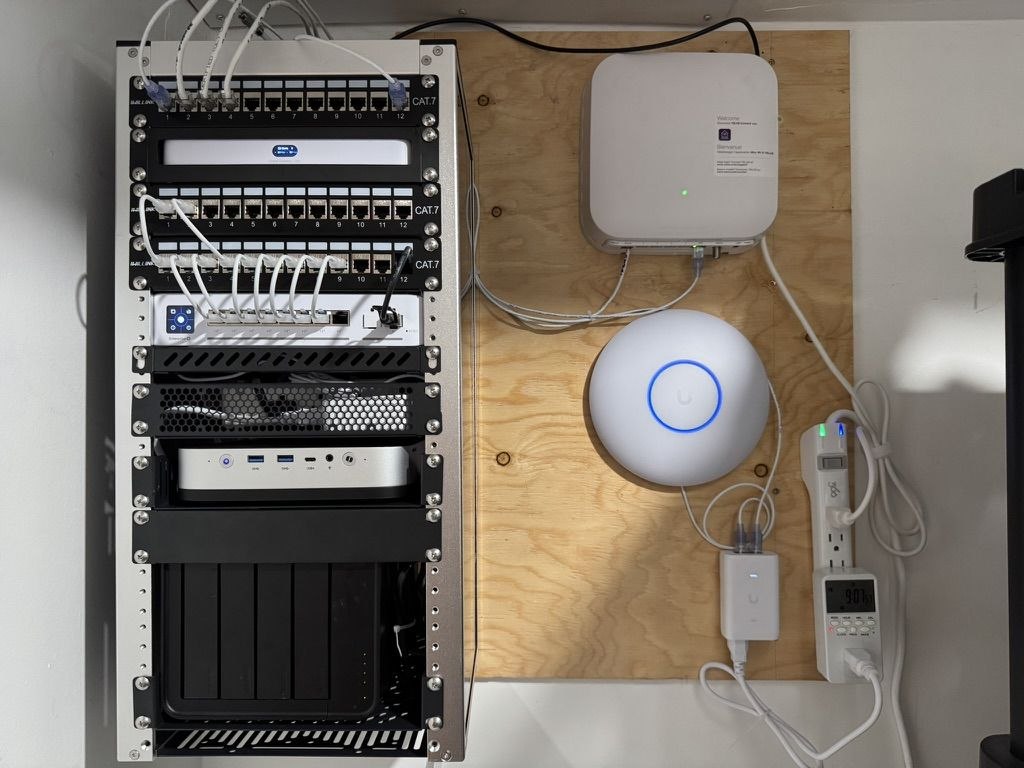
Top models by quality
Browse all modelsFind the right model for your hardware
Already know your rig? Pick it here and see exactly which models you can run locally, with honest speed estimates and cloud-pricing comparisons.
01 - Select your hardware
click to compare02 - Save your rig (free)
Sign in with GitHub to save your hardware. New here? We'll guide you through picking your rig - Mac, multi-GPU (up to 8x), or custom specs - then show you exactly which models you can run locally.
Sign in with GitHub - freeWho's running what
See all 31 →Yuchen Jin (Databricks): DeepSeek V4.1 Flash is his pick for easy and moderate tasks - fast and cheap. Databricks reports customers cutting spend dramatically by shifting 20% of internal coding traffic from Claude/GPT to open models.
Yuchen Jin (Databricks): GLM-5.3 is cheap and fast, suited to high volumes of non-complex coding tasks. Part of Databricks engineers' shift to open models as daily drivers.
Databricks AI systems CTO Yuchen Jin: Kimi K3 is the best open-weight coding model in their experience. Databricks serves it at 239 tok/s, the largest open model they have hosted, and ranks #1 for K3 inference speed on Artificial Analysis.
Yuchen Jin (Databricks): DeepSeek V4.1 Flash is his pick for easy and moderate tasks - fast and cheap. Databricks reports customers cutting spend dramatically by shifting 20% of internal coding traffic from Claude/GPT to open models.
Yuchen Jin (Databricks): GLM-5.3 is cheap and fast, suited to high volumes of non-complex coding tasks. Part of Databricks engineers' shift to open models as daily drivers.
Statuses: confirmed official source reported credible third-party, not officially confirmed testing evaluating, not deployed.
Curated and source-cited, not a scraper. Built a rig worth sharing? Browse shared builds →.