The Spark cluster
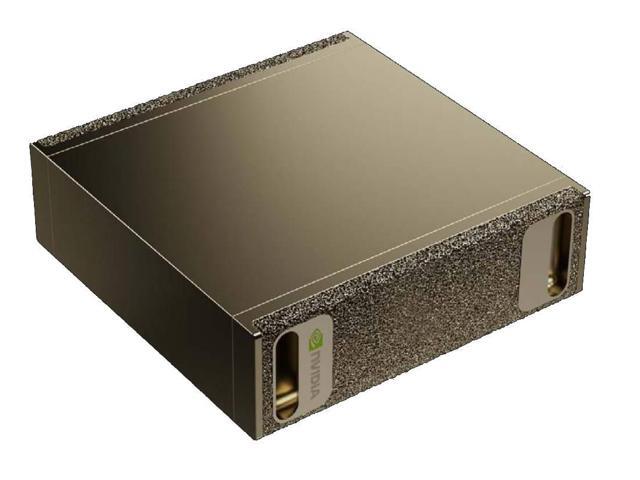
Three DGX Sparks, 384GB pooled over ConnectX: the compact rack that punches up.
NVIDIA's answer to the Mac Studio: 128GB of coherent memory per box, and the interconnect to pool them. Three Sparks cost less than one 512GB Ultra and bring CUDA-native inference, which matters for the newest model drops that land on NVIDIA stacks first. The trade: noisier, hotter, and per-dollar memory is worse than Apple. Assembly is cabling, not carpentry.
Teams and developers who batch jobs, run agent fleets, or test against NVIDIA-first releases the day they ship. Anyone whose work needs 200GB+ of model weights and a machine room that fits under a desk.
last check: Oct 3, 2026
The parts
What it runs
The 2.8T class: Kimi K3 needs 700GB at 2-bit. Tensor parallelism across three boxes adds latency in single-user chat; batch jobs hide it, conversation does not.
About 720W for the trio at load, datacenter-adjacent loud. A closet with a door or a garage shelf is the right home. The install is two Ethernet cables and power; the tuning is software.
The question that keeps showing up on X: I have 20 to 30 thousand dollars, what do I buy? One answer is a single 512GB box that runs everything. The other is a rack of NVIDIA that trades silence for CUDA-native speed. This tier is where those two answers live, priced and compared.
See the $30k tier →