The starter
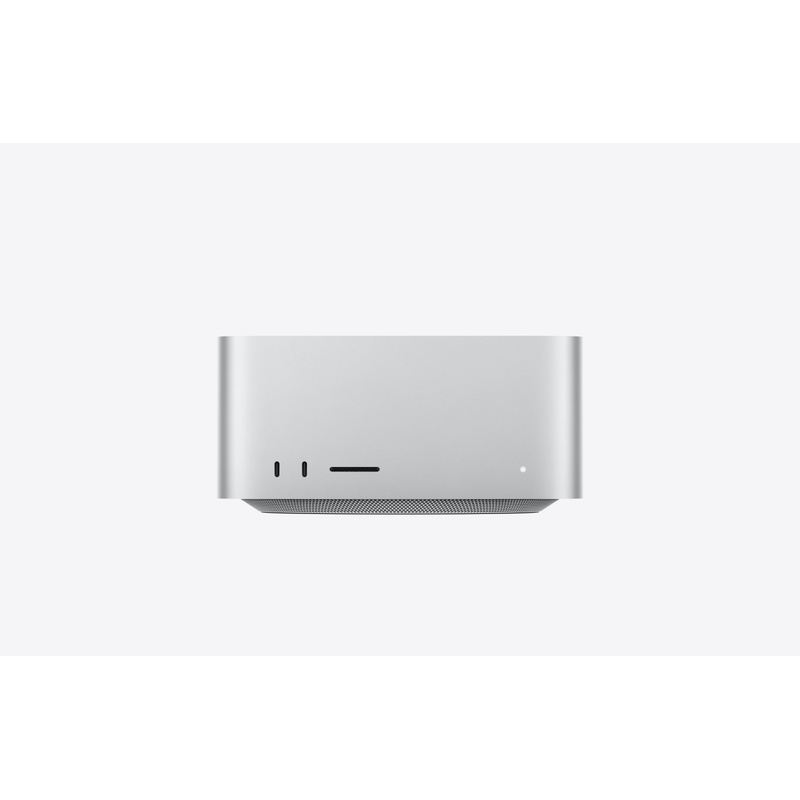
M4 Max 64GB: every decision model, every small LLM, real work, done.
The build that answers 'is local even worth trying yet?' with yes. 64GB runs the 27B class comfortably and the sub-10B class at hundreds of tokens per second. For the decision-model wave (Jev-style routing, Laya, form fillers) this is more machine than you need, which is exactly the point.
You want local AI to be a weekend project, not a hobby that eats your garage. You run a small voice assistant, triage your email with a decision model, search your own documents, and keep every byte of it inside the house. If your last build was a gaming PC in 2015 and you just want the box to work, this is your tier.
first check: next Monday
The parts
What it runs
The 300B+ MoE class: GLM 5.3 Flash needs 80GB of weights at 2-bit and this box has 64GB total. Video generation is also out of reach - a 5090 belongs one tier up.
About 140W under load, quieter than the laptop it replaces, and it plugs into the wall like a lamp. No UPS required, no thermal planning, no case fans to pick.
This is the tier where local AI becomes boring, which is the highest compliment. The box is silent, the answers are fast, and the models are big enough that you stop asking what a model can do and start asking what you want done. Your writing assistant, your code reviewer, your document librarian, your form-filler: all local, all day, on hardware that uses less power than the monitor next to it.
See the $5k tier →