The desk build
One M5 Ultra 96GB: the 27B-and-under sweet spot with 200B-class quantized guests.
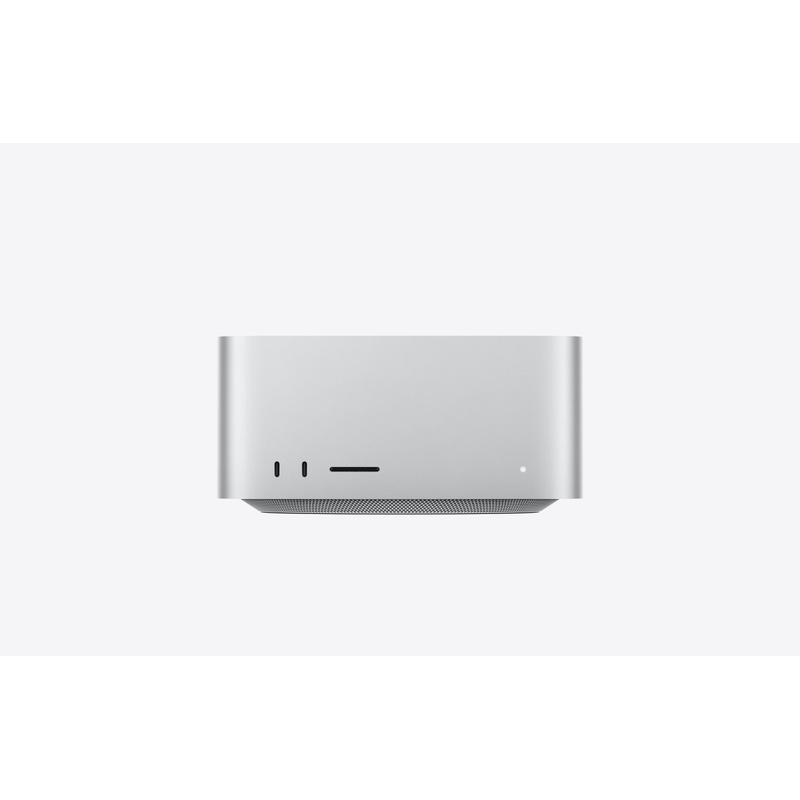
For most people actually running local AI daily, this is the honest machine. 96GB of unified memory runs every small decision model natively, the 27B multimodal class at full precision, and the 100B+ class in 4-bit when you are patient. It is silent, it uses less power than the monitor next to it, and it costs a quarter of the flagship build.
You run local AI every day and you are tired of thinking about it. The desk build is the machine you stop noticing: it is silent, it sips power, and it answers in 100 to 200 tokens per second. Coding assistants, document search, the decision-model wave, photo tagging, a private chat that never leaves the house. If you work from home, this is the tier where local stops being a demo.
first check: next Monday
The parts
What it runs
DeepSeek V4.1 Flash at any quant (552B total parameters is 138GB even at 2-bit). GLM 5.3 Flash runs only at 2-bit with short context - fine for chat, wrong for long documents. Video generation wants an NVIDIA card.
Roughly 180W under full load. It is fan-cooled but effectively silent at desk distance, uses less power than your monitor, and needs nothing but a power cable. One UPS if you are paranoid about a writing session.
Open the case. This is where local AI becomes a hobby with a parts list: two GPUs, a power plan, and the fastest single-machine inference you have ever seen. New models land on CUDA stacks first, and this build is standing on the loading dock when they arrive.
See the $12k tier →