Qwen4-Max went live on 16 November as a closed weight model and the most capable model Alibaba has shipped. Buried in the same announcement is the line local users were waiting for: “Open-weight, smaller-scale models from the Qwen4 series will soon be released to developers worldwide.”
That is the entire promise. No parameter counts, no release date, no licence. The specific number everyone is quoting comes from somewhere else.
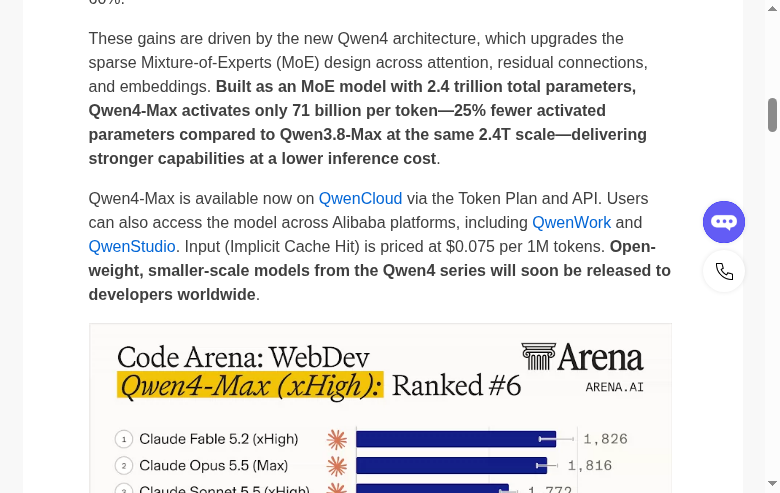
The closing paragraph of Alibaba’s launch post, with the open weight promise and the same paragraph’s pricing detail. Screenshot: Alibaba Cloud.
Where the 27B figure comes from
Tooling vendor Unsloth posted on 16 November: “Qwen announces smaller Qwen4 models will be released soon. Qwen4-27B will run on 16GB RAM setups.” The post has 3,725 likes and it is the reason a 27B number is circulating.
Unsloth did not cite a Qwen document for the size. Alibaba’s own post says “smaller-scale” and stops there. A 27B model at four bits per weight is roughly 16GB, so the arithmetic checks out, but the size itself is a vendor’s summary of an announcement rather than a specification.
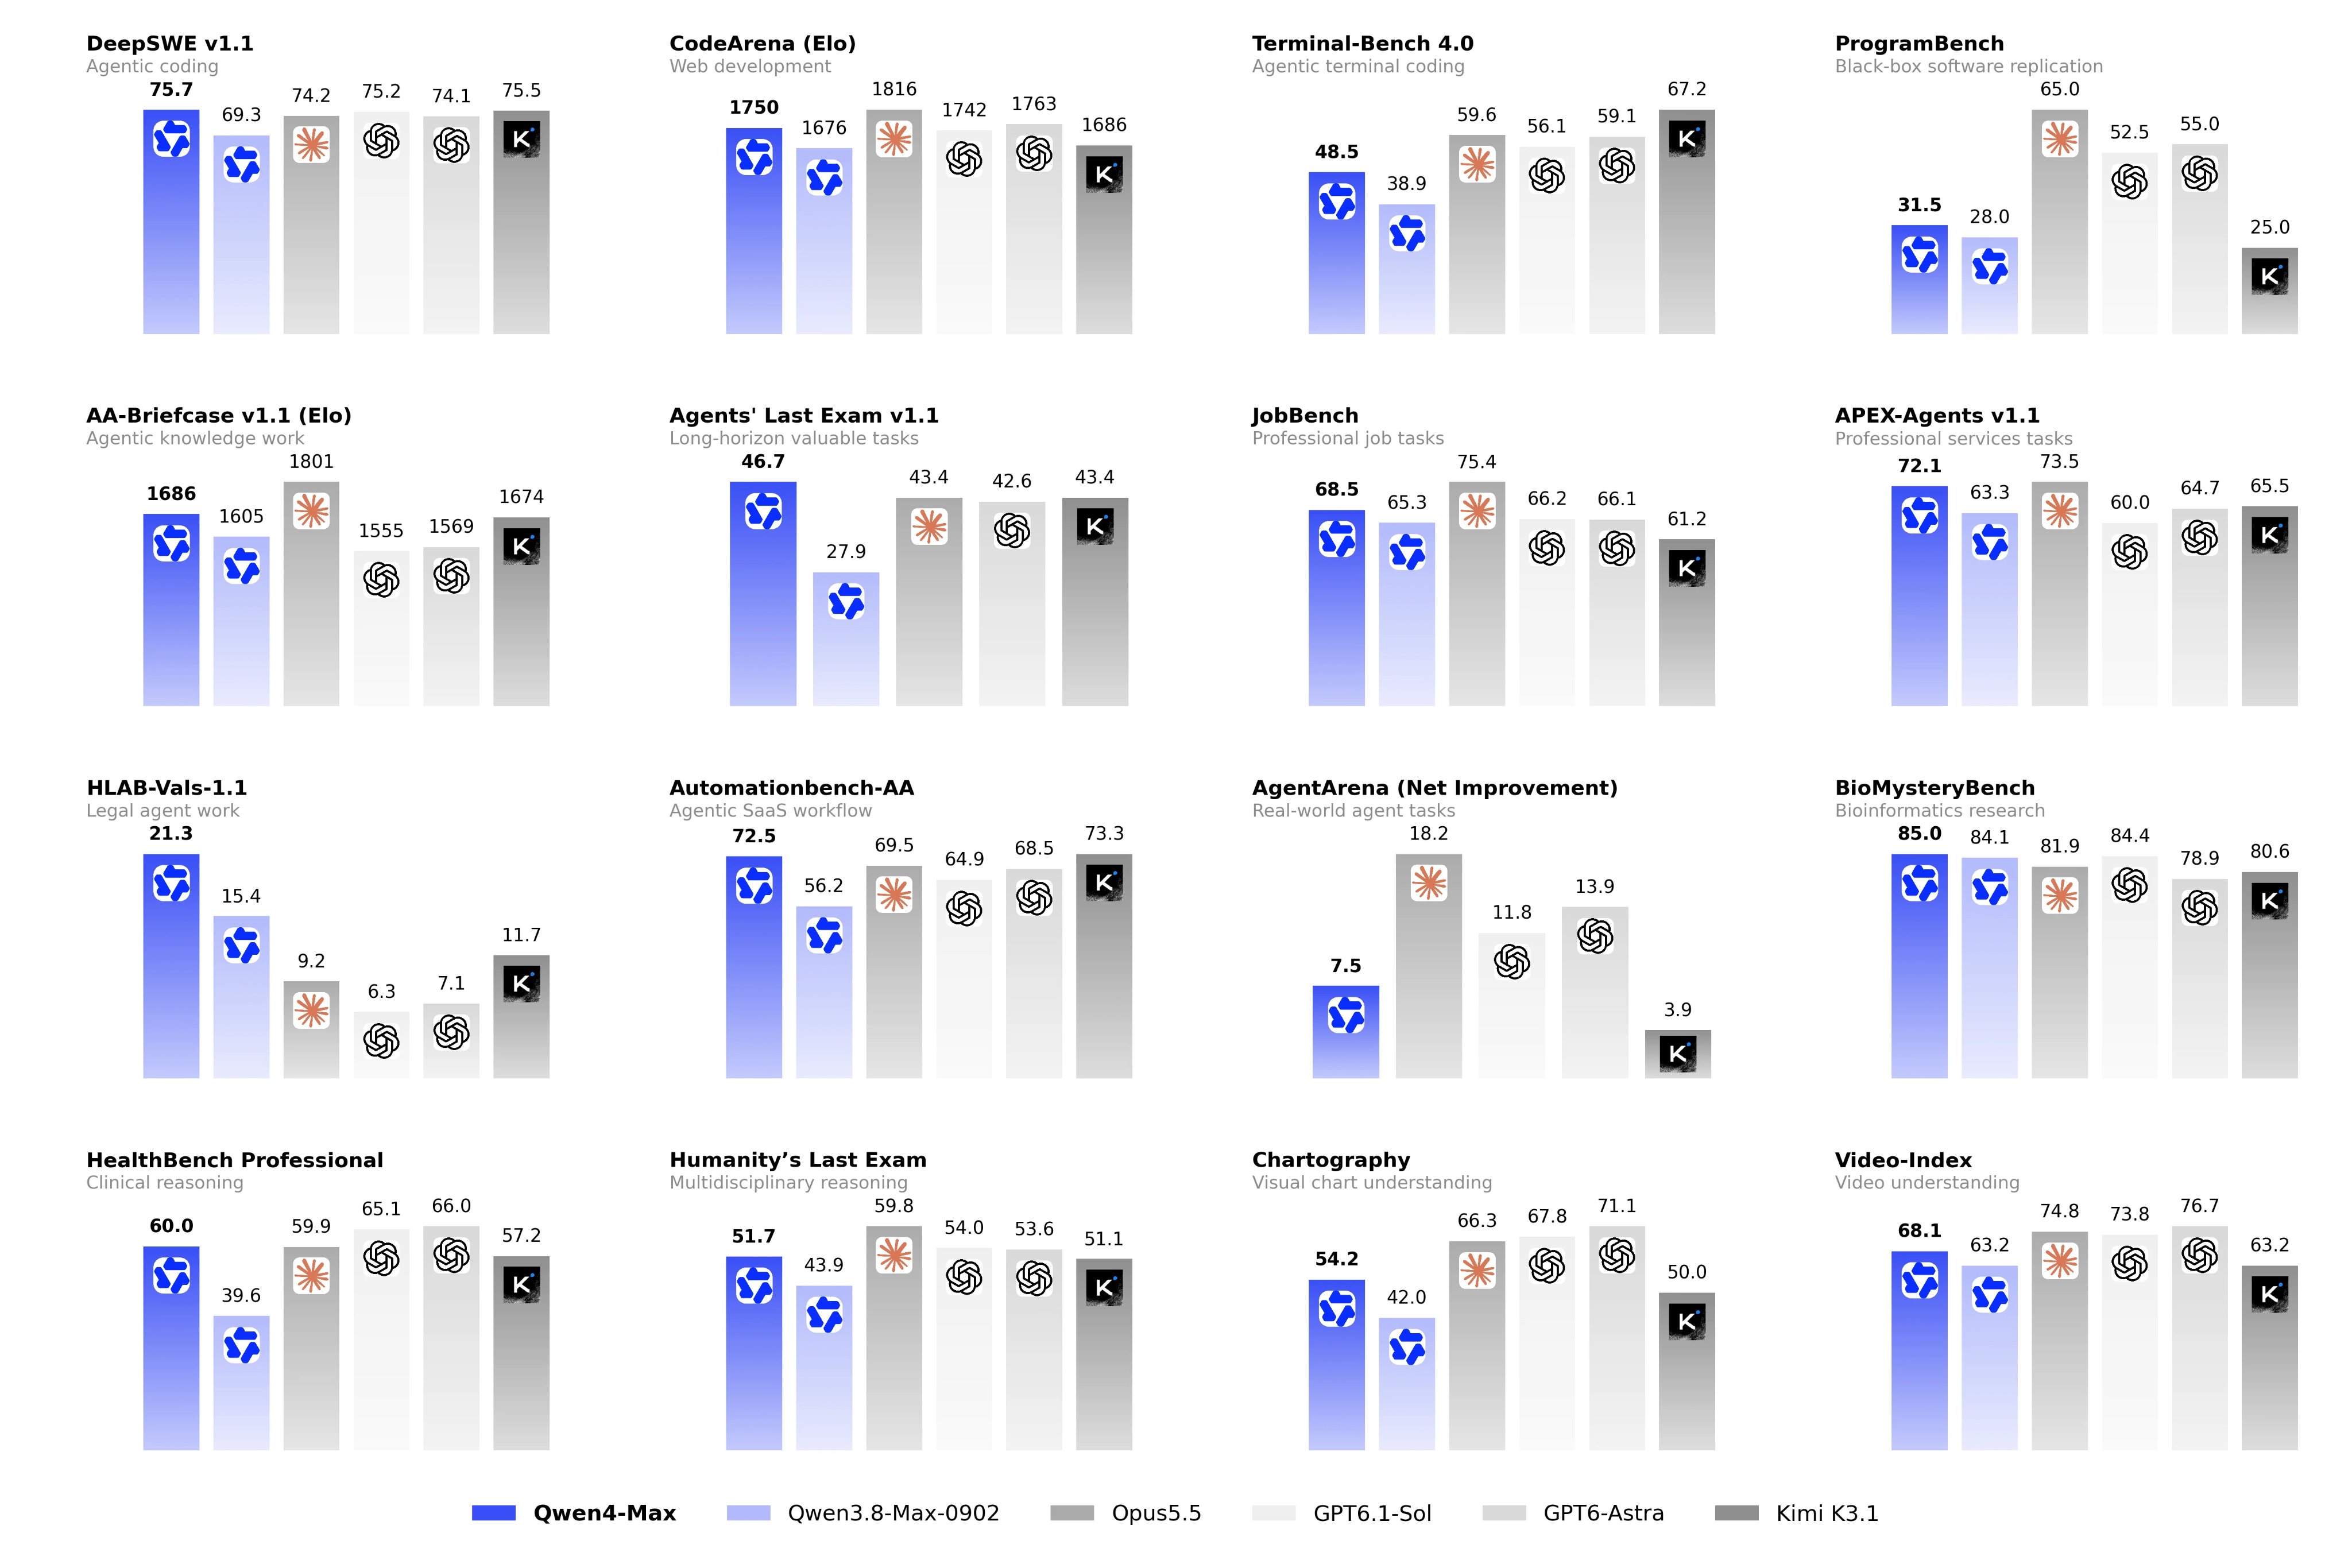
The launch card Alibaba published with its announcement. Image: Alibaba Qwen.
What shipped instead
Qwen4-Max is a mixture-of-experts model with 2.4 trillion total parameters that activate 71 billion per token, which Alibaba describes as 25% fewer activated parameters than Qwen3.8-Max at the same scale. It is available through QwenCloud’s Token Plan and API, with implicit cache hits priced at $0.075 per million input tokens, and it ranked 6th on Code Arena’s WebDev leaderboard against Claude Fable 5.2 at the top.
None of it helps anyone with a 16GB card. What matters to them sits one paragraph above.
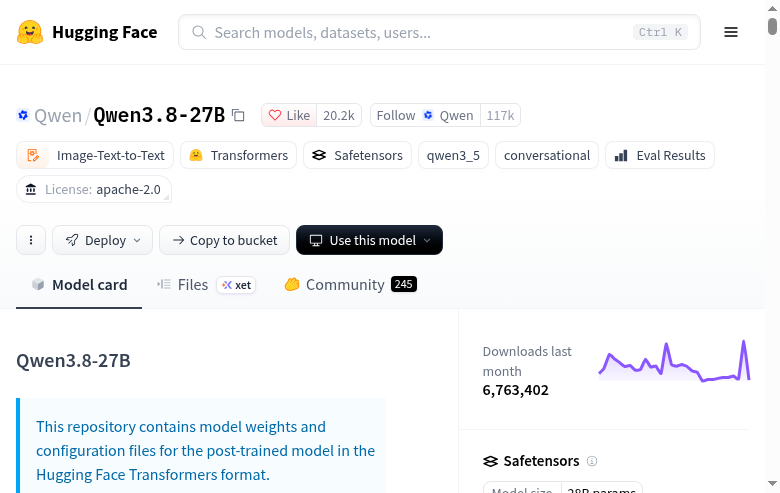
Qwen3.8-27B, the model the promised release would replace, at 6,763,402 downloads in the last month. Screenshot: Hugging Face.
The gap it would fill
Qwen3.8-27B has 6,763,402 downloads in the past month under Apache 2.0, and it is the model most local users settled on when the 24GB class became affordable. Nothing in the Qwen line has replaced it since, and the loudest complaint in the Hacker News thread announcing Qwen4-Max was exactly that: there is nothing between 24GB and 100GB of VRAM to take its place.
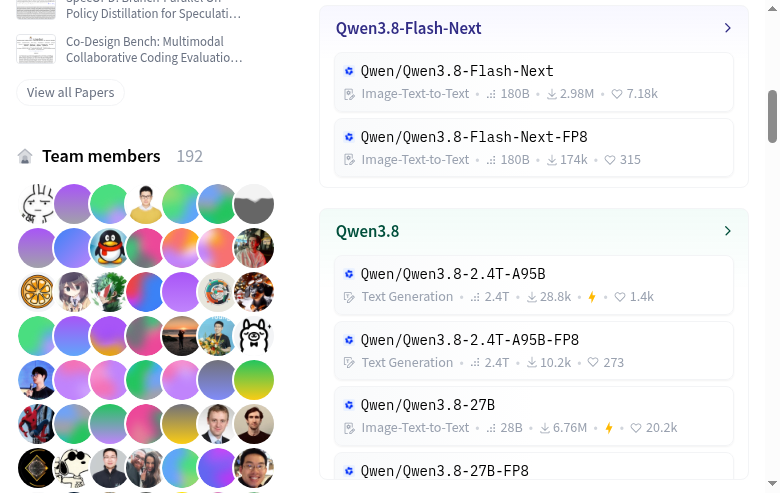
Qwen’s organisation page on 16 November. The newest repositories are all Qwen3.8. Screenshot: Hugging Face.
Careful with what you find today
Searching Hugging Face for Qwen4 returns 680 results, and none of them belong to Qwen. They are community uploads named for a Qwen4-27B that does not exist, several dated before the launch announcement, carrying labels like uncensored, one bit, or NVFP4. Treat any of them as unverified until a repository appears under the Qwen organisation.
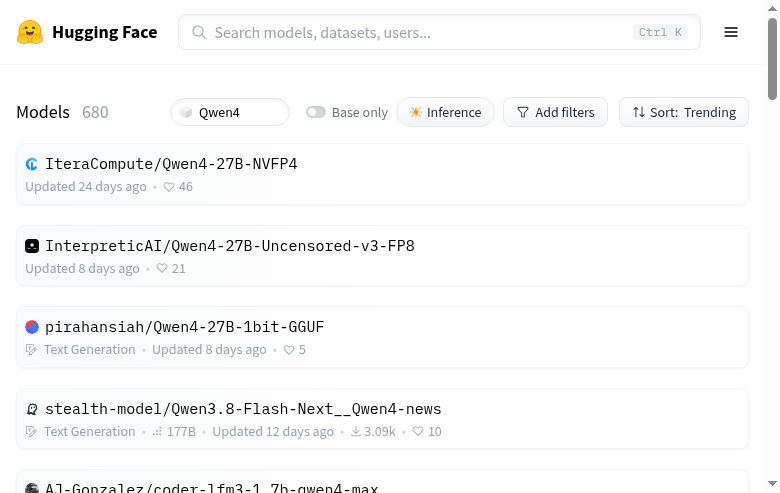
The Qwen4 search results, 680 models, all community uploads. Screenshot: Hugging Face.
What would settle it
A repository under Qwen/ with safetensors, a licence, and a model card that names the parameter count. Until that exists, the 27B figure is a sensible inference from a vendor’s arithmetic, and the release date is a sentence.
Qwen has shipped open weights for the mid tier of every generation so far, which is why the promise carries weight. The useful question is which size arrives first, not whether one arrives.
Sources: Alibaba Cloud: Qwen4-Max launch - Qwen4-Max announcement post - Unsloth on smaller Qwen4 models - Qwen3.8-27B model card
Related on this site: Thinking Machines releases Inkling 2 Small weights
Discussion
Be the first to commentStart a discussion
Got a take on this, a rig to show off, or a benchmark that says otherwise? Sign up and start the thread - your comment publishes instantly once you're in.