Baseten built its name as the inference platform you rent instead of running models yourself. Today its research arm, Base Labs, shipped two models of its own, and the category it chose is telling: decision models, the category this site tracks, where open weights currently lead the closed frontier.
What shipped
Two models, both full fine-tunes of Qwen3.5, both MIT on HuggingFace:
-
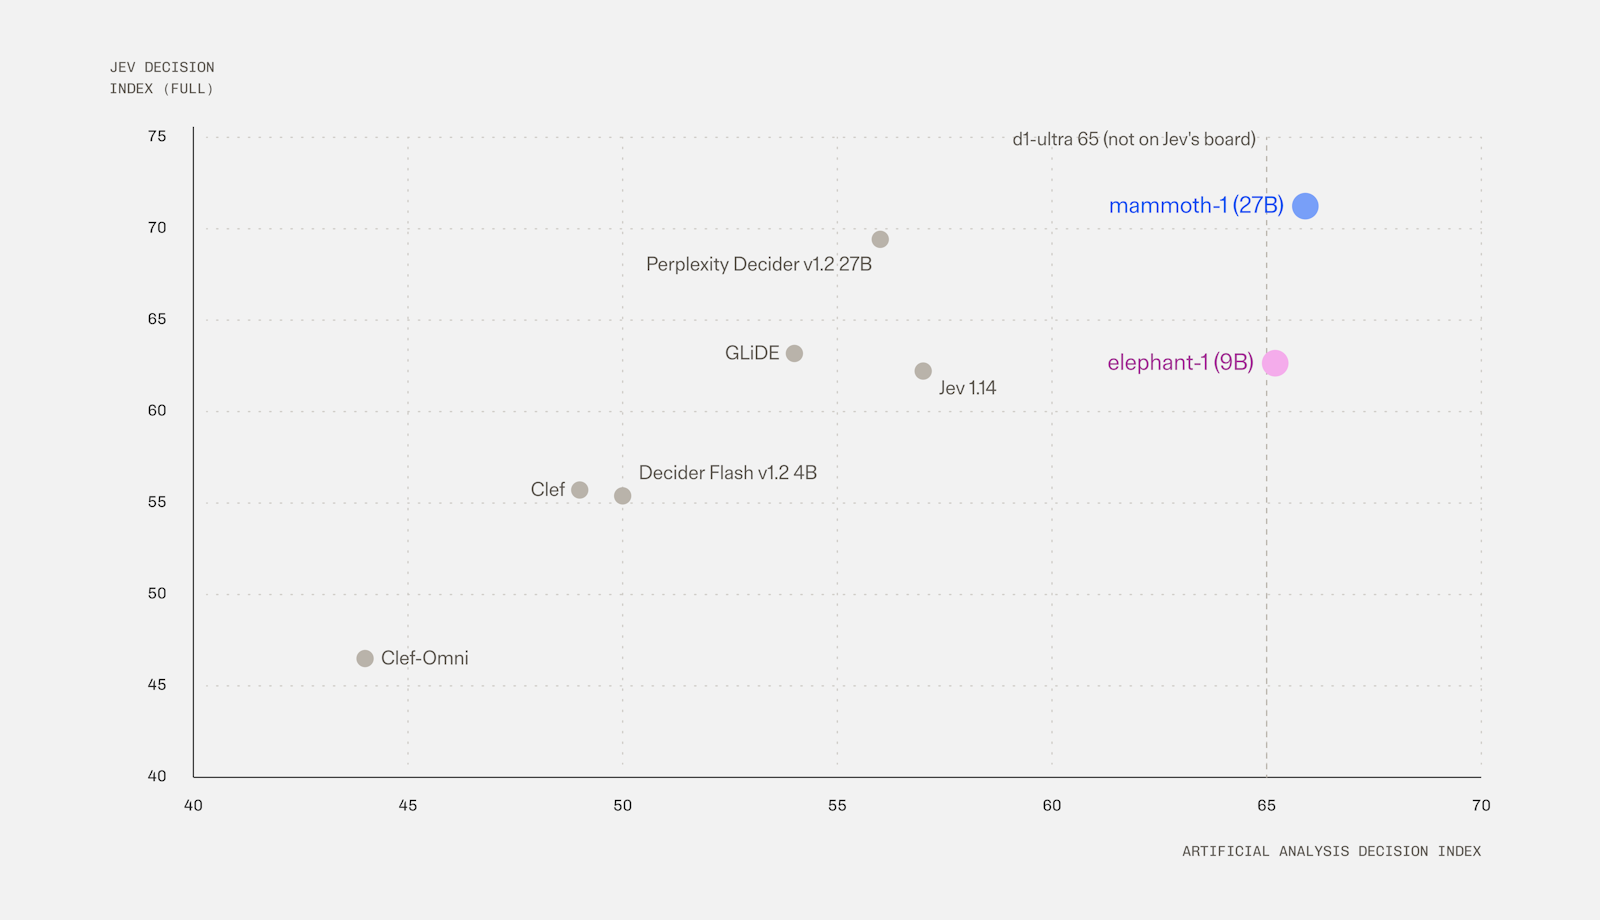
mammoth-1 (27B): Base Labs claims #1 of 208 on the Jev Decision Index, the open leaderboard this site follows
-
elephant-1 (9B): claimed best under 15B, also above Jev
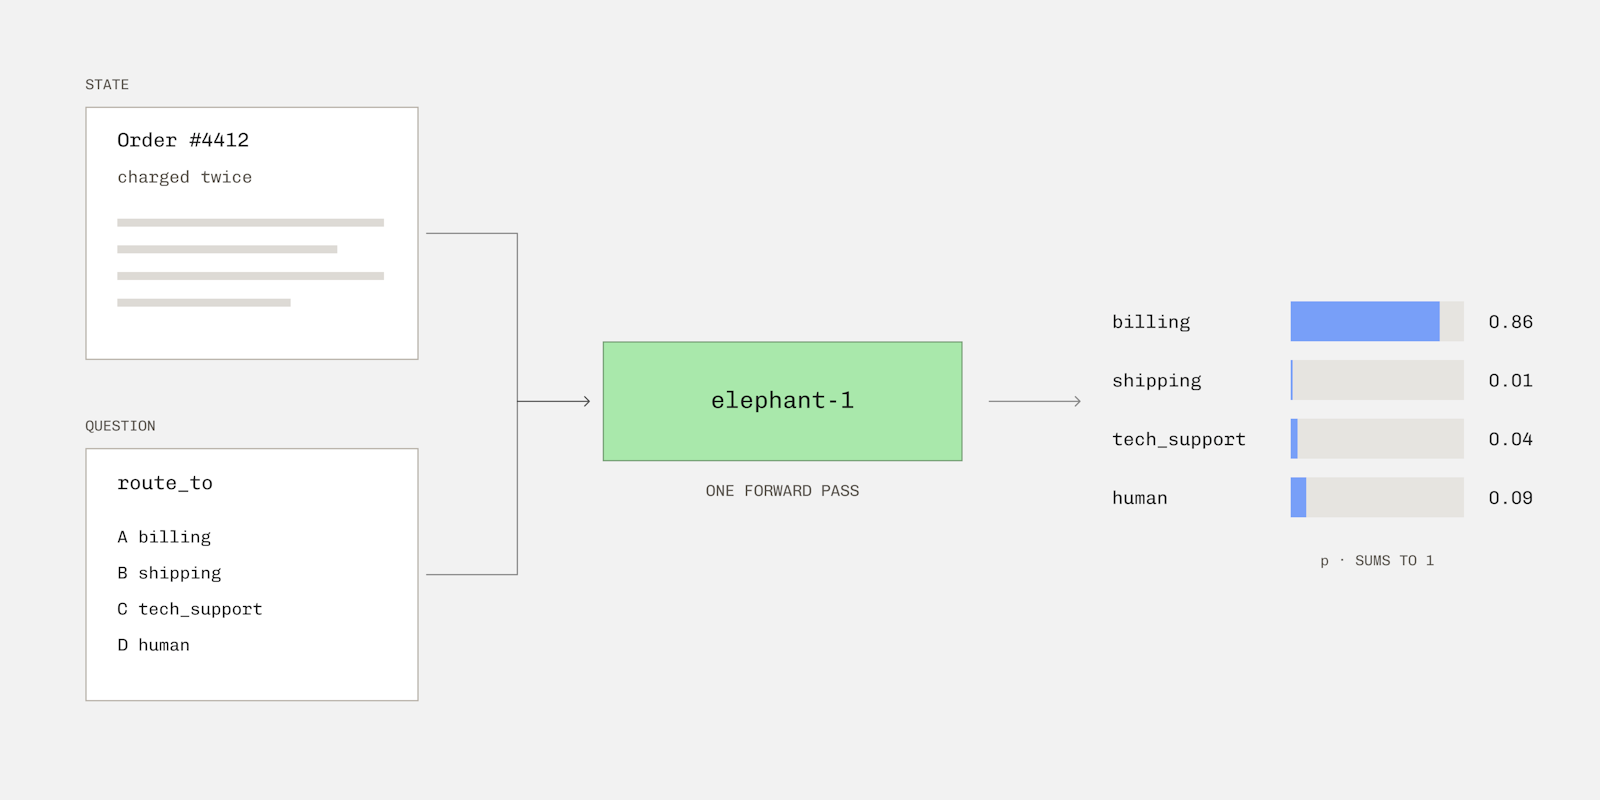
The schematic above is the whole category in one picture: hand the model a support ticket and a question with a fixed set of answers, and it returns a confidence number per option in ONE forward pass. No tokens are generated. That is a decision model.
Why this category matters
Decision models do the boring work of AI infrastructure: routing tickets, classifying intent, scoring leads, gating agents. They are cheap to run (one forward pass, no token stream), easy to evaluate (probabilities sum to 1), and they fail in visible ways. The category is where a 9B model can beat a 500B generalist, which is why Baseten entering it with open weights is a genuine signal rather than a marketing swing.
The honest status, as always on this site: the Jev-index ranking is the vendor’s claim and the index itself is vendor-linked. The weights are real, MIT, on HuggingFace, and the community GGUFs already exist. Verify on your own hardware before believing the leaderboard.
Sources: Base Labs’ announcement (labs.baseten.co), the baselabs model repos on HuggingFace (MIT).