Recursive shipped open weights on Tuesday that most AI labs would call a moonshot: a 40-billion-parameter coding model that fits and flies on a 48 GB Apple laptop, built largely by their own automated research system rather than a large human team. The weights are Apache-2.0 on HuggingFace, day one, official GGUFs included. Within 48 hours it sat at #3 on HF trending with 600 likes and 1,900 downloads on the base repo alone.
What Flint is
Flint TLDR: an open source MoE coding model that runs entirely on a 48 GB laptop. It enables offline agentic coding at home: repo work, bug hunts, feature code, tests, no API in the loop. The difference between Flint and regular LLMs is that it is a 40B MoE with only 2.5B active parameters per token, so it leaves headroom for tools, context, and other models on one machine while carrying 40B-class coding knowledge.
Concretely: 40B total parameters, 2.5B active per token, trained from scratch by Recursive’s research pipeline. The INT4 and NVFP4 quantized GGUFs are official, so the weight files you download at midnight are the ones the vendor benchmarked, not a community re-quant.
The number that matters: 131 tok/s on the machine already on your desk
Recursive’s local throughput chart is the piece of media worth studying. On an Apple M4 Pro with 48 GB of unified memory, Flint MLX decodes at 131.22 tokens/second on short context (68.89 normalized through the 128K window). The llama.cpp build decodes at 87.98. On an RTX Spark, Flint’s NVFP4 build hits 155.82 tok/s short-context.
The frontier chart puts that in context against what a 48 GB box can otherwise run: Qwen3.8 27B, Qwen3.5 3.5B, Muse Glimmer 4, Laguna XS 21B, Gemma 4 31B. Flint’s dot sits up and to the right of all of them, which is the entire marketing argument in one picture: you trade a small quality gap for a decode speed you can feel.
Where does it actually score? SWE-bench Verified 74.2 with the BF16 checkpoint (69.2 on NVFP4; note the quantized build trades about 5 points of benchmark quality for the memory savings). Terminal-Bench 2.1: 54.9 BF16. SWE-bench Pro v2: 89.7. IFBench: 89.2. IFEval: 95.1. These are vendor-measured numbers on NVIDIA-hardware peers and local peers, all on one zero-based scale, with dense models from 3.5B to 33B as the comparison set.
Built by AI, out loud
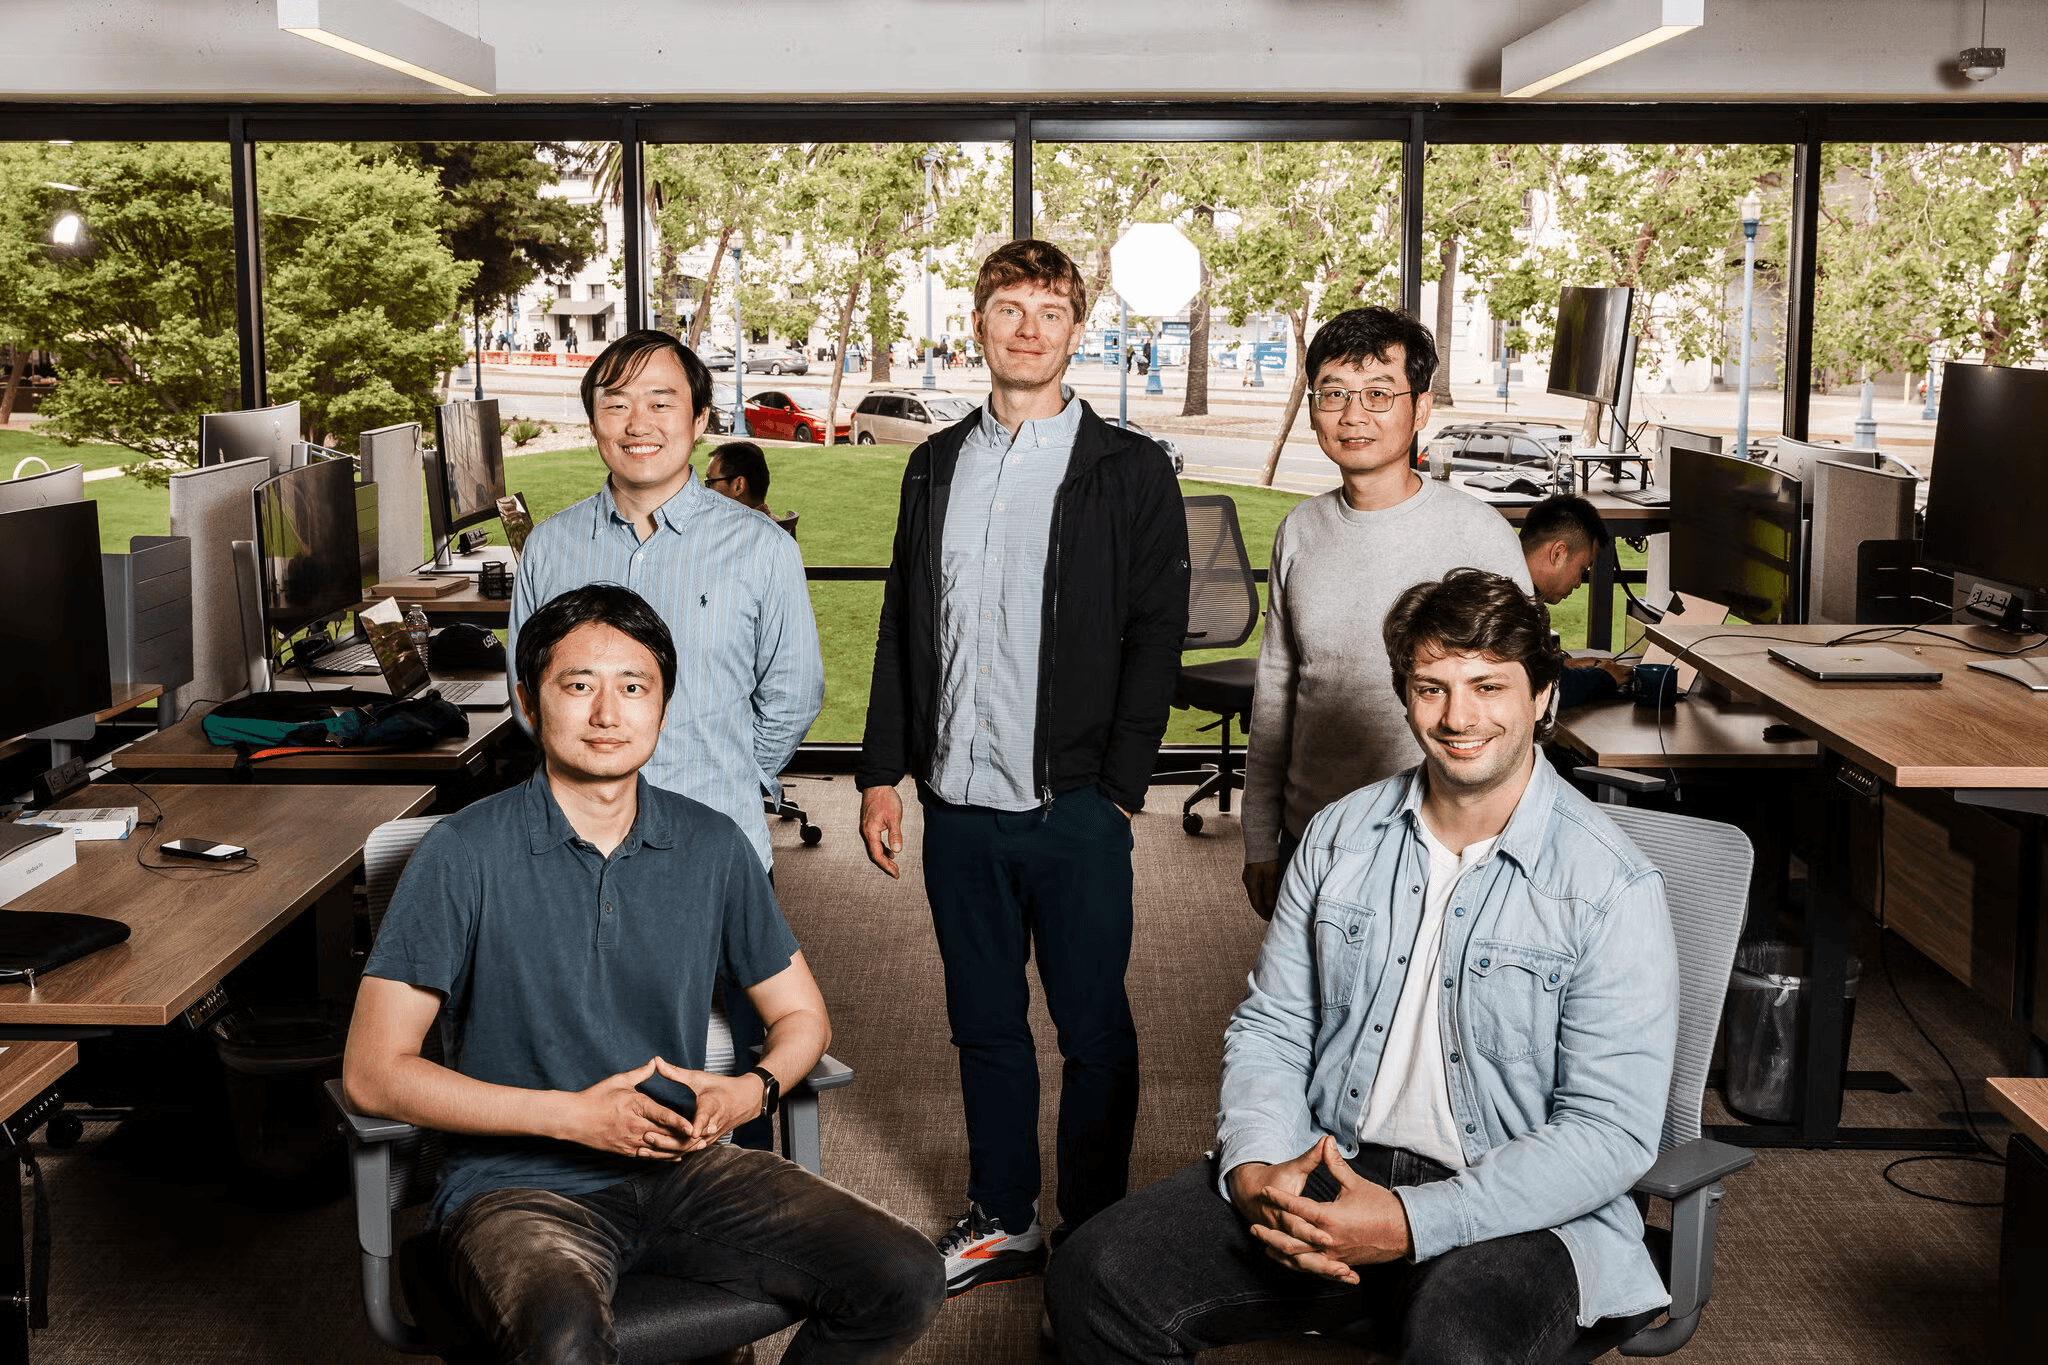
The Wired profile (Oct 21) puts the recursive loop at the center of the story: Recursive’s automated research system produced most of Flint’s capabilities in under four months, and the company is explicit that the loop is the product. The team photo and founder portrait Recursive released alongside the announcement carry the confident-of-the-pitch energy you’d expect.
The honest caveat: “built largely by AI” is the vendor’s framing and it is unfalsifiable from outside. What IS verifiable: the model exists, the weights are on HuggingFace, the benchmark charts are published, and anyone with 48 GB can check every number on this page tonight.
Fit math for the tiers
At 2.5B active parameters, decode speed is real-world fast, but residency is a total-parameter problem: 40B total at 4-bit is about 20 GB; at INT4 the official GGUF runs around 22 GB with context. That leaves 26+ GB free on a 48 GB machine for KV, embeddings, and the agent’s other models, which is the actual point of the MoE design: one laptop running a coding agent, a small local model, and tools without swapping.
On Apple’s 64 GB tier, the same model gets headroom for a bigger KV pool and longer context windows; on 32 GB machines, the NVFP4 build is the only comfortable fit and context shrinks accordingly.
The week of recursive self-improvement
The reason to care is larger than one checkpoint. Wired framed Flint as the first credible “AI built the AI” release with open weights anyone can test at home. If the benchmarks reproduce on your machine tonight, the story stops being a claim and becomes a fact you own.
Sources: Recursive’s announcement (recursive.com/updates/introducing-recursive-flint), the RecursiveSI model repo on HuggingFace (Apache-2.0), Wired’s Oct 21 coverage.
Related on this site: the engine catalog has the runtimes Flint’s GGUFs run on; the budget builds tier table shows which machines carry 40B total comfortably.