Meta description (draft): Strata serves 180B Flash-Next from a 12GB gaming card plus system RAM: 94 tok/s on a 5070, 179 on a 5090, 45.7 on $350 of used datacenter iron. —
Strata shipped 1.0-grade releases this week (repo Niko1221/Strata, MIT, C++, 12,493 stars in eleven days) with an HN front page at 825 points under the headline “Run Qwen3.8 Flash Next (125B) on consumer hardware at 100T/s”. The claim set is big, so before writing anything this site did what it does: pulled the README, the paper, the community bench folder, and the live Qwen repo config, and checked each number against what independent hands measured.
The model is the one this site has tracked since August: Qwen3.8-Flash-Next, the 180B-weight MoE that fires only 6B parameters per token (the live config reads 512 local experts with 10 active plus shared expert; the 51B n-gram embedding table does deterministic host-memory lookups instead of per-token compute). That asymmetry is the whole trick: weights are big, compute is small, and the cache is tamed by the Gated DeltaNet plus Qwen Sparse Attention hybrid. Strata’s engineering job is to make that asymmetry usable on a consumer box, and its mechanism matches the model’s shape: the GPU holds the few thousand hottest of the model’s 24,576 experts, system RAM holds all of them, the SSD holds the lookup table, and a draft model guesses ahead so the big model checks 1.6 to 1.8x sooner.
The numbers, with their sources kept honest
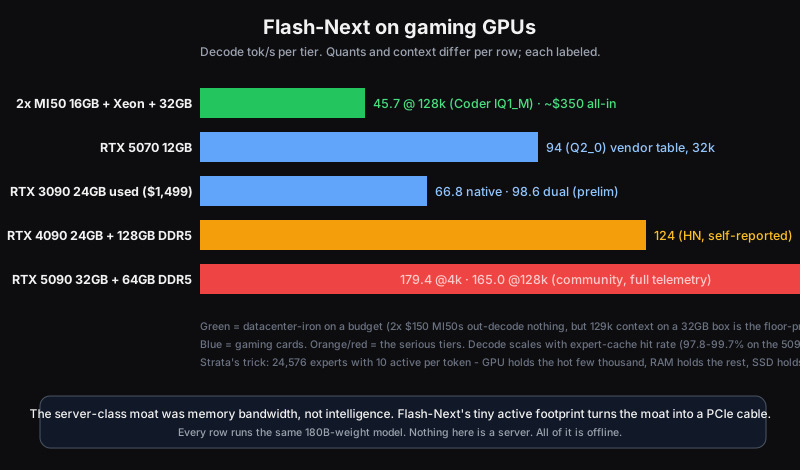
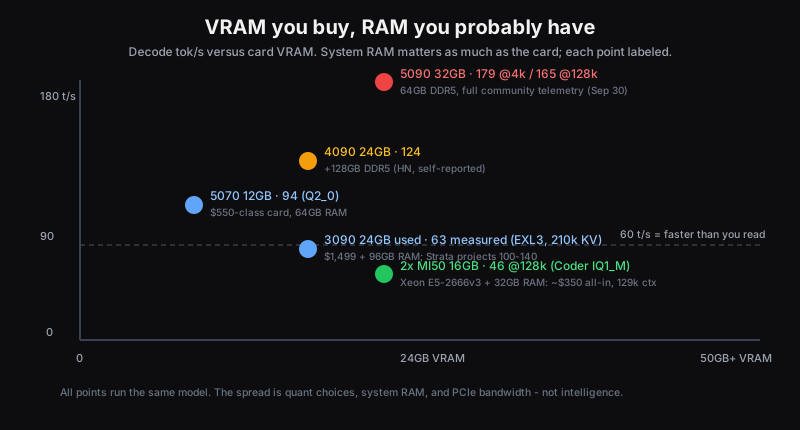
The README’s own tables: RTX 5070 12GB writes 94 tok/s at Q2_0 (2,650 tok/s prompt reads), 79 at IQ2_XS, 53 at IQ3_S; RX 9070 XT 16GB writes 60 at Q2_0; a third-party preliminary bench pins native Strata at 66.8 tok/s single-3090 Coder IQ1_M at 32k (three-run median) and 98.6 on the auto dual-GPU split, against the 100 to 140 projection and 0xSero’s separate 63 tok/s EXL3 serve. The title-vs-body mismatch the HN thread caught (a 4090 headline over tables showing a 5070) is real in one draft artifact and worth naming: the independent verification carries the post’s real weight.
Three independent measurements support the numbers. A community 5090 bench (Sep 30, full telemetry, per-run JSON, three runs per context length) measured 179.4 tok/s at 4k prompts falling only to 165.0 at 128k, with prompt processing at 5,779 tok/s at 128k and expert-cache hit rates of 97.8 to 99.7 percent. An HN commenter runs 124 tok/s on a 4090 with 128GB DDR5. And the budget datapoint this site loves most: two AMD Instinct MI50 16GB cards, a Xeon E5-2666v3, and 32GB RAM (about $350 of used iron) hold 45.7 tok/s decode at 128k context on the Coder variant - long-context, multicard, offline, at second-hand-warehouse prices.
What it actually takes on your desk
The installer measures your machine and picks the quant: 32GB of RAM runs the Coder half-expert variant (91 percent of the full model’s SWE-bench Verified, per its authors), 64GB runs IQ2_XS comfortably, and Strata loads 35 to 55GB into RAM with the card locked during a 1-to-3-minute startup. Serving is OpenAI-compatible on localhost:8080 with an Anthropic-compatible /v1/messages path, so Claude Code and Codex point at it with zero glue; there is an MCP server so your coding agent installs and drives Strata itself, thinking effort is a menu (off/low/medium/high), and vision works on NVIDIA cards today (AMD reads pictures on Linux through the CPU). First prompt of a chat reads at about one minute per 30k tokens; follow-ups start in seconds.
The same model runs on an M5 Ultra at 108 tok/s and on a 3090 EXL3 serve at 63 tok/s per user - the tier chart is now continuous from $350 of used rack iron to $6,795 of new gaming card, and none of it is a server. The server-class moat was always memory bandwidth, not intelligence; Flash-Next’s tiny active footprint turns that moat into a PCIe cable.
The reach already shows the shape: Roundtable Space’s summary of the thread (300 likes) put it plainly - “Your gaming PC can now run a 125 billion parameter model. You don’t need a server” - the exact question this piece answers with per-tier numbers.
Sources: Strata repo - HN thread, 825 pts - Community 5090 bench - Community 2x MI50 bench - Qwen3.8-Flash-Next - 0xSero’s 3090 EXL3 recipe
Related on this site: Qwen3.8-Flash-Next - The value pick - M5 Ultra: tokens per watt - The only hard budget cap on agents is a box you own
Discussion
Be the first to commentStart a discussion
Got a take on this, a rig to show off, or a benchmark that says otherwise? Sign up and start the thread - your comment publishes instantly once you're in.