Local AI guides
Run local AI on your own hardware - practical, cost-driven guides.
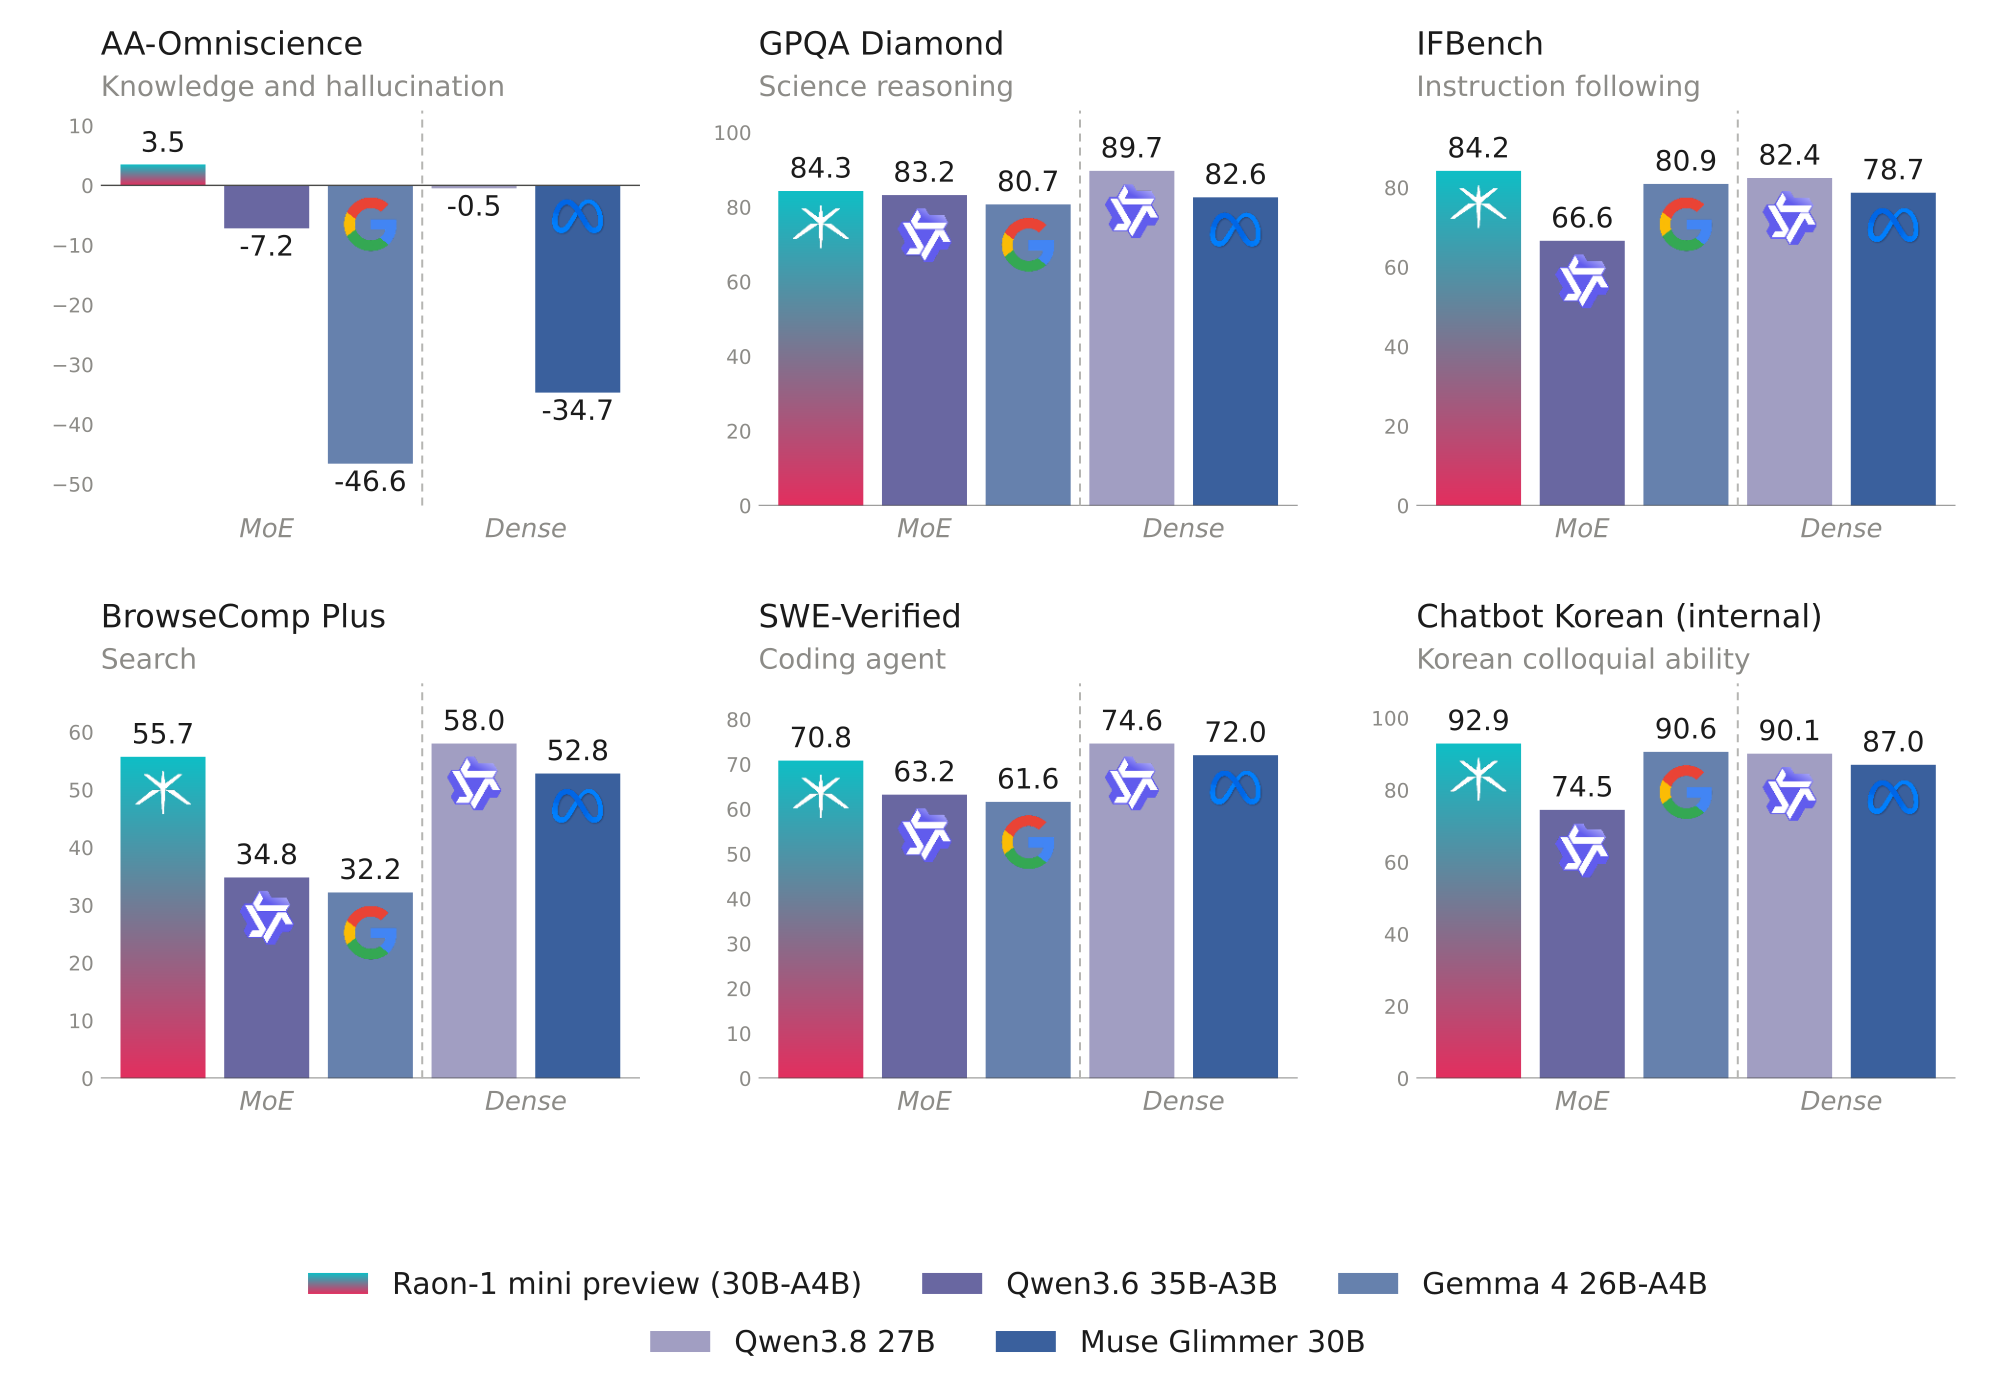
Raon-1 mini: Krafton's 30B open model with thinking
Raon-1 mini is a 30B MoE with 4B active under Apache-2.0. Thinking channel and DFlash2 draft ship with it: NVFP4 for one RTX 5090, MLX for Apple, GGUF too.
Oct 23, 2026
Recursive Flint: 40B coding model for 48 GB laptops
Flint is a 40B MoE coding model with 2.5B active under Apache-2.0: 131 tok/s on an M4 Pro, 156 on an RTX Spark, built largely by an automated research system.
Oct 23, 2026
NVIDIA Flare: a Rust server for Spark-class local inference
NVIDIA's Flare serves SM120/SM121 GPUs from a Rust runtime built by PyTorch compile. Bolt 74B on one card, Qwen3.8 and DeepSeek V4.1 Flash recipes.
Oct 21, 2026
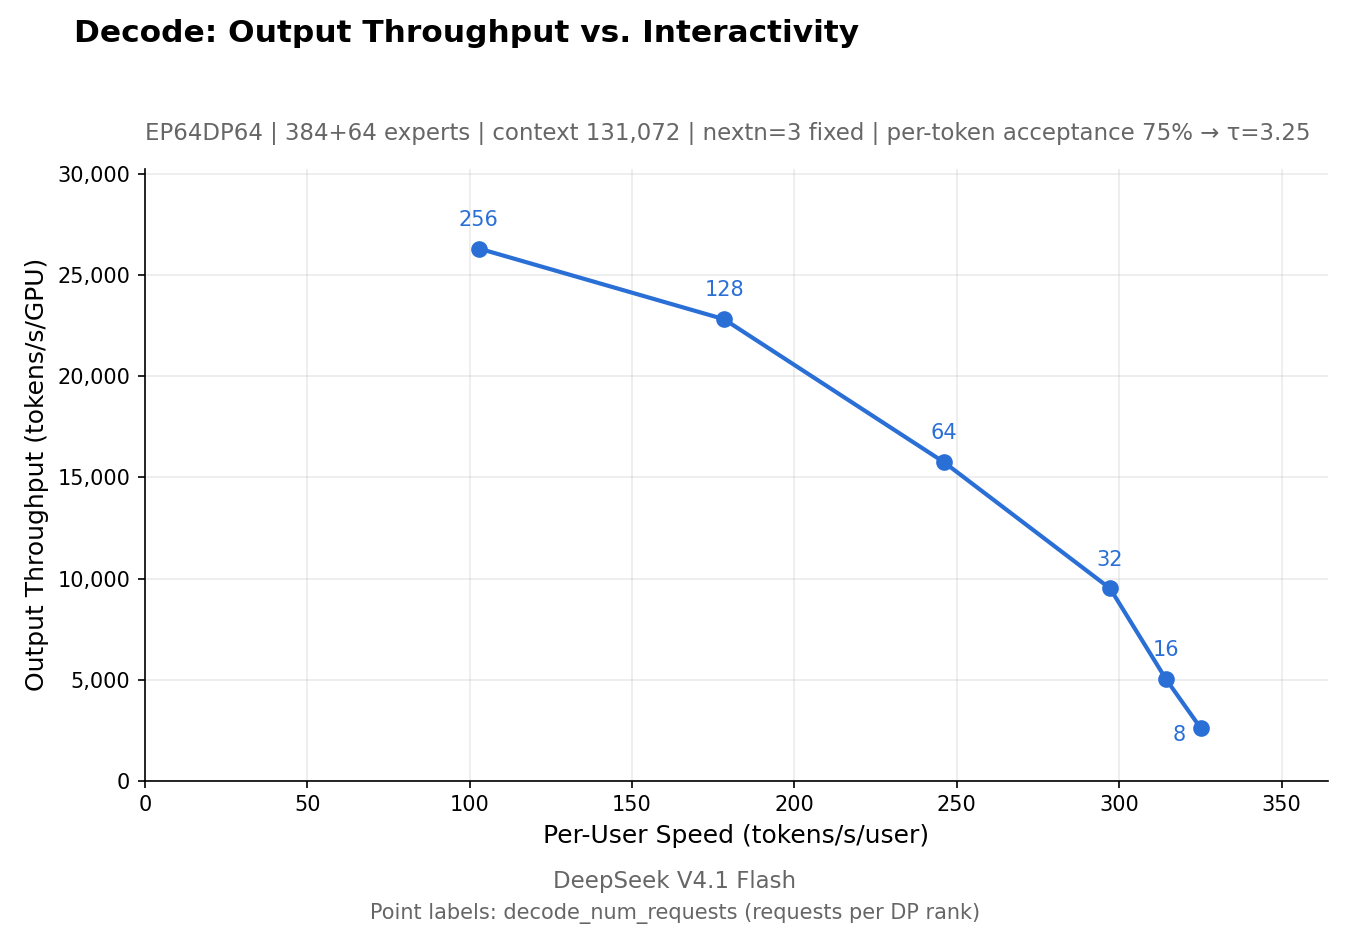
DeepInfer: DeepSeek open sourced its inference engine
DeepSeek's production inference engine DeepInfer is now open source under Apache-2.0, serving the V4.1 Flash model at scale on SM100 and Ascend 950.
Oct 20, 2026
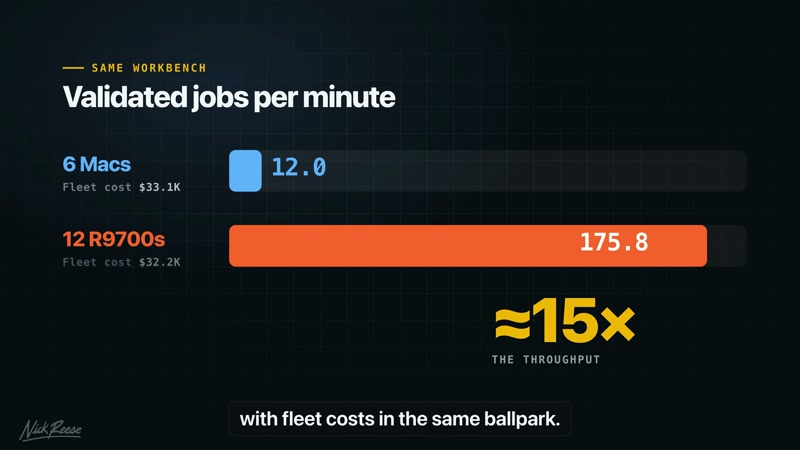
The refusal tax: one business's $32,201.72 cloud answer
OpenAI's model started refusing his gun directory's normal work, so Nick Reese built 12 R9700 GPUs in-house for $32.2k and got 15x the throughput. The receipts.
Oct 19, 2026
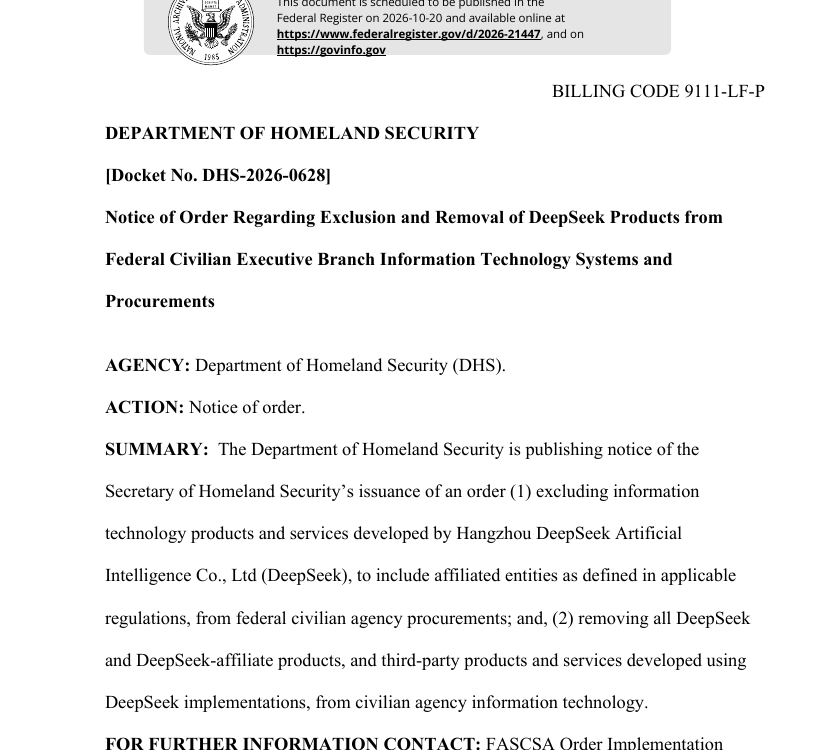
DeepSeek banned out of US civilian IT, built-on tools too
A DHS FASCSA order removes DeepSeek and every third-party tool built on it from federal civilian IT. The MIT weights stay legal elsewhere.
Oct 19, 2026
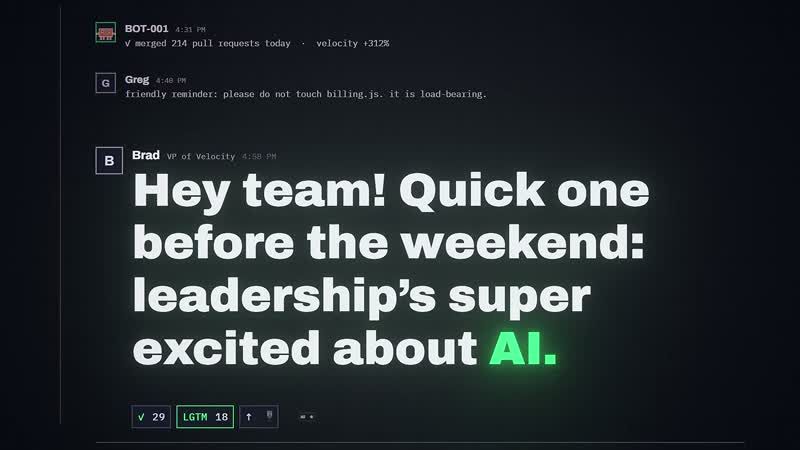
LGTM: the AI satire video that approves itself 1,363 times
Degenerative Pixels' LGTM music video hit 1.2M views satirizing AI code review, and the joke is layered: Claude Opus 5.5 wrote the whole animation as code.
Oct 19, 2026
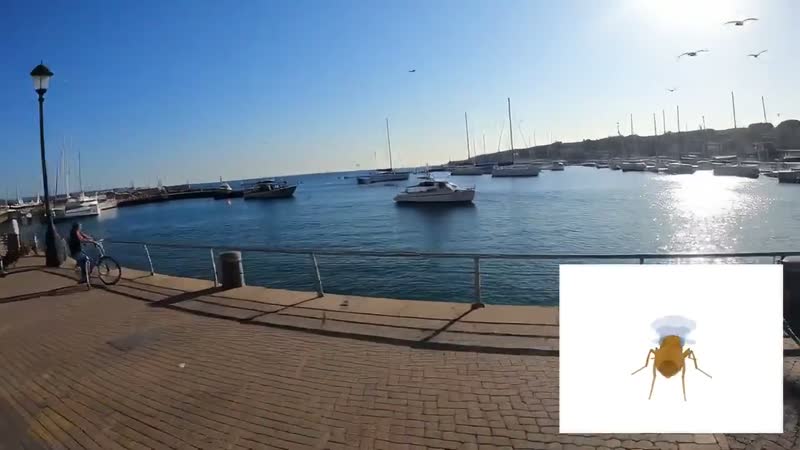
The fruit fly is AI's favorite research animal now
Six years of fly-brain mapping ended with the whole CNS in 2026, and builders put it in Doom, Mario 64 and a world model. What the demos actually show.
Oct 19, 2026
OpenCode's gateway breach: one legacy box, 1.4% of keys
OpenCode Console lost 1.4% of users' provider keys to a distillation attack through a legacy system. The gateway is the attack surface, and the bills hit users.
Oct 19, 2026
Twenty-one ways to run a model locally: the engine catalog
The runtimes catalog now carries 21 verified local inference engines. The pick-by-hardware map: GGUF, Metal, GPU serving, NPU specialists.
Oct 18, 2026
China's export draft leaves published weights alone
China's Announcement 48 draft adds 23 AI technologies to export review, but published weights are exempt. What 2T and top-10 thresholds mean for open models.
Oct 18, 2026
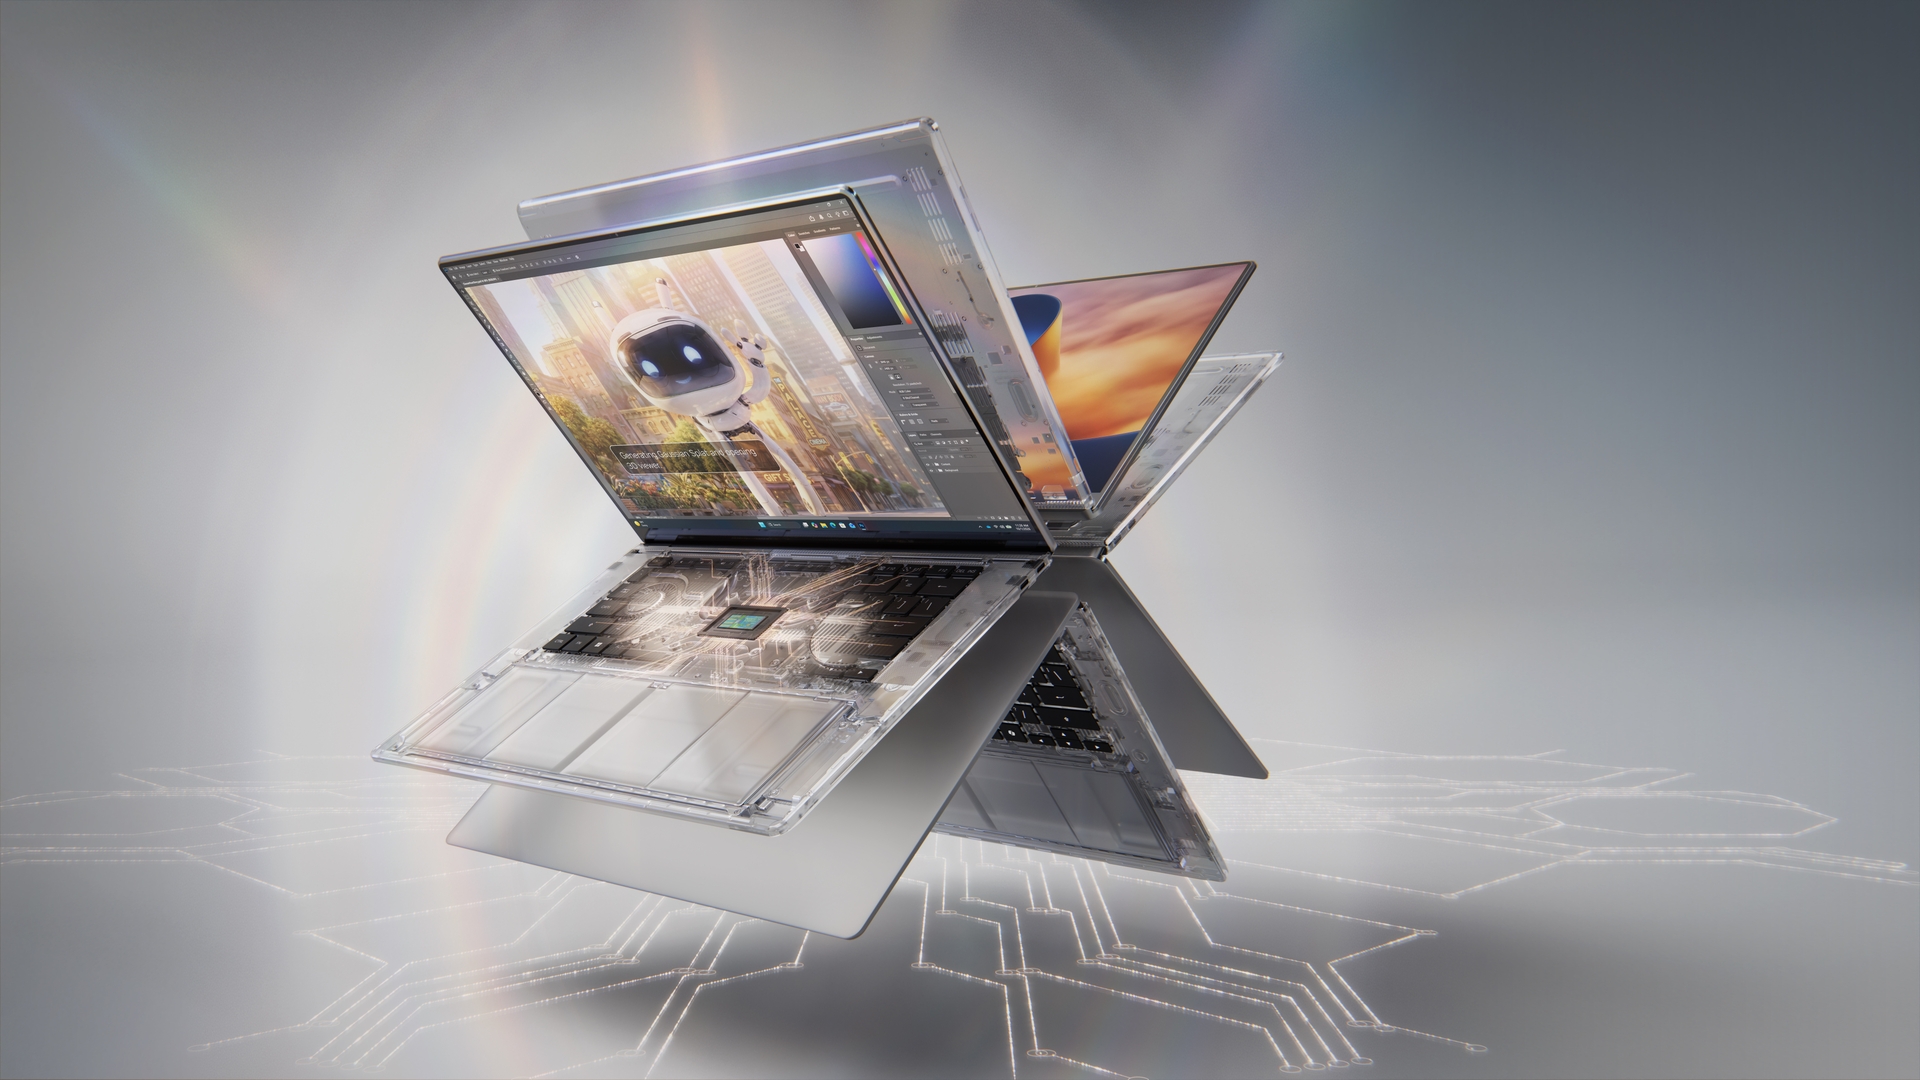
Hermes Agent ships on NVIDIA's RTX Spark launch
RTX Spark laptops ship October 16 with Hermes Agent on the launch slide, pickable in Windows' agent setup flow, running Qwen 3.8 27B local on 128GB.
Oct 17, 2026